01 / PREDICTIVE WORLD MODELCoRL 2026 · Accepted
PLaW-VLA
PLaW-VLA: Predictive Latent World Modeling for Vision-Language-Action Policies
Co-first author
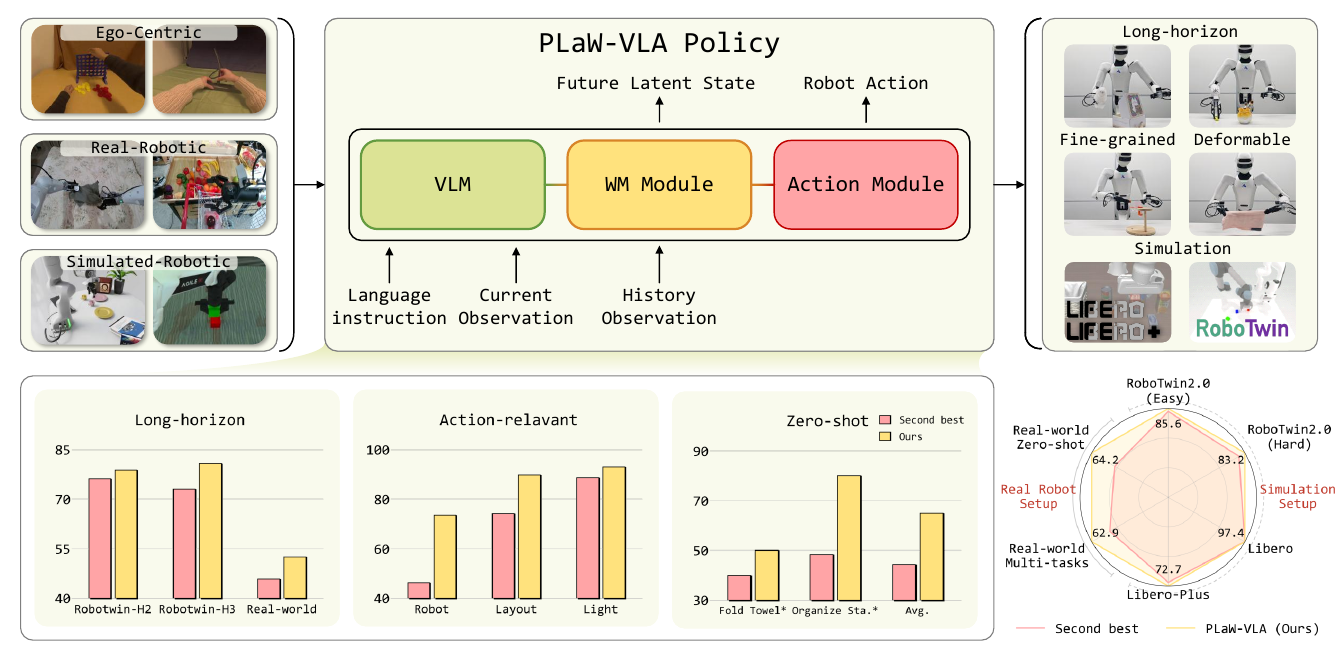
Predicts future states in a pretrained visual latent space rather than reconstructing pixels and couples state prediction with action generation. Average success reaches 97.4% on LIBERO and 72.7% on LIBERO-Plus, with long-horizon, fine-grained, and deformable-object manipulation tested on Astribot S1.